agent: 让模型真的干活
为什么做这个模式
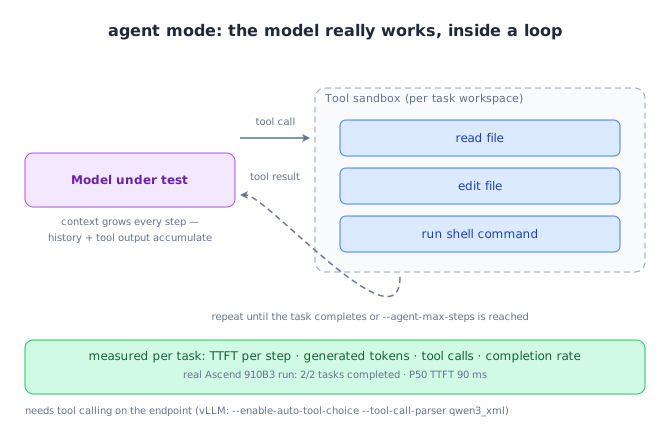
合成提示词只是对 Agent 流量的猜测。这个模式让被测模型真的调用工具 —— 读文件、改代码、执行 shell —— 于是流量具备 Agent 工作的形态:突发的工具循环、不断增长的长历史,以及「任务完成或没完成」这个结果。
怎么用
bash
clawperf --mode agent \
  --endpoint http://localhost:8000/v1 --model Qwen3-0.6B \
  --tokenizer /mnt/model/Qwen3-0.6B \
  --agent-tasks 8 --agent-max-steps 12 --agent-max-tokens 512 \
  --agent-shell-timeout 30 \
  --output results_agent.json
Warning
需要端点开启工具调用。vLLM 需要 --enable-auto-tool-choice --tool-call-parser qwen3_xml(解析器名称随模型系列而定)。
关键参数
| 参数 | 作用 |
|---|---|
--agent-tasks |
并发运行的编码任务数。 |
--agent-max-steps |
每个任务在被截断前允许的工具调用步数。 |
--agent-max-tokens |
任务内每次模型调用的生成 token 上限。 |
--agent-shell-timeout |
单条 shell 命令允许的最长秒数。 |
--agent-task-file |
用自定义任务替代内置任务集。 |
--agent-workdir |
每个任务工作区的根目录。 |
完整参数列表(含默认值)见完整参考。
真实输出
真实的工具调用 Agent 运行。
clawperf report results_e2e/agent.json --print
Report saved to: results_e2e/agent.md
# ClawPerf Benchmark Report
| Field | Value |
| Model | `qwen3` |
| Endpoint | `http://110.138.0.3:9155/v1` |
| Backend | vllm |
| Mode | `agent` |
| Tasks | 2 |
| Max Steps | 8 |
| Setup Time | 0.08s |
| Bench Time | 16.05s |
## Verdict: ✅ GOOD
- **TTFT (P50):** 90ms — instant (GOOD)
- **Task completion:** 100%
## Key Findings
- Task completion rate: 100% (2/2)
- P50 TTFT: 90ms — instant
## Summary
| Task | Steps | Finished | Wall(s) | In Tok | Out Tok |
| 0 | 8 | yes | 16.00 | 9,663 | 1,497 |
| 1 | 2 | yes | 4.87 | 1,130 | 479 |
## Methodology
<details>
<summary>Click to expand</summary>
- **TTFT** (Time to First Token): wall time from request send to first content chunk on the wire.
- **TPOT** (Time Per Output Token): decode time / output tokens, excluding prefill.
- **ITL** (Inter-Token Latency): gap between consecutive output chunks.
- **Prefix cache hit rate**: token-level, read from the backend's Prometheus counters (start/end delta). Not
  request-level.
- **Verdict thresholds**: TTFT GOOD ≤3s / OK ≤10s; throughput GOOD ≥30 tok/s / OK ≥15 tok/s.
- **Compaction**: when context exceeds ``max_context_tokens``, history is cleared and the user prefix is incremented.
- **Decode throughput** isolates generation speed from prefill (excludes TTFT).
- **Wall-clock per-user throughput** uses real start/end timestamps, not summed per-request latencies.
</details>
怎么读结果
- 任务完成率是第一眼要看的:跑得快但任务从没做完,不代表服务快。
- 每个任务的步数与 token才是 Agent 工作的真实成本 —— 决定预算的是它们,不是提示词长度。
- 每步 TTFT 说明工具循环的时延到底由服务端还是由工具主导。
其他模式: scenario · hitrate · slo · trace · record & replay